The Great PDF Triage: How OpenDataLoader PDF Ends the RAG Accuracy Tax
By blending deterministic Java heuristics with surgical AI strikes, Hancom’s hybrid engine solves the multi-column "scrambled text" problem without a GPU-heavy budget.
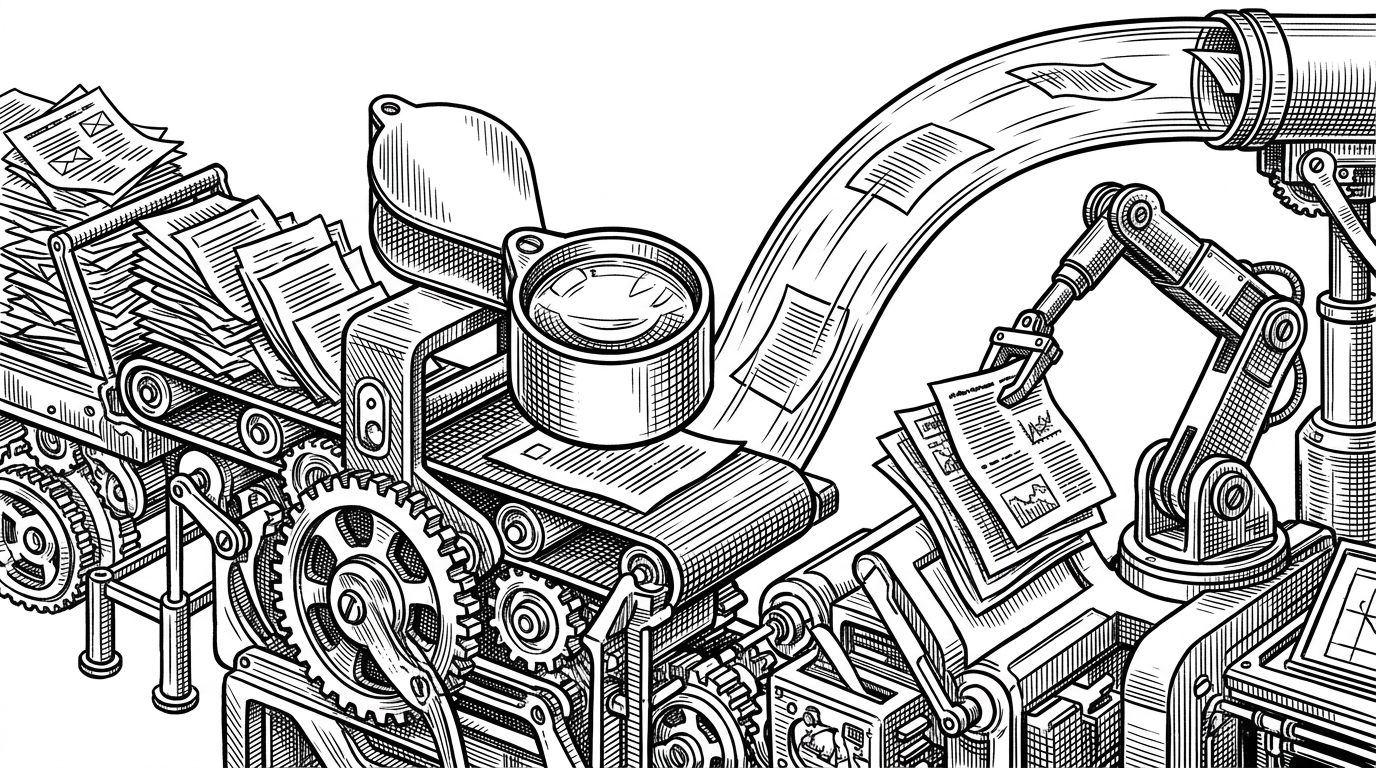
- The TriageProcessor routes simple pages to a fast Java engine while reserving expensive AI models for complex layouts.
- A deterministic XY-Cut++ algorithm restores correct reading orders in multi-column documents without requiring a GPU.
- The engine generates Tagged PDFs to ensure enterprise documents meet PDF/UA accessibility standards for screen readers.
- OpenDataLoader reduces processing costs by handling 90 percent of standard document workloads on local CPU hardware.
The Two-Column Hallucination
Retrieval-Augmented Generation has a silent killer. It is not context window limits or embedding quality. It is reading order.
When a human looks at a two-column academic paper, the flow is obvious. We read down the left side, then jump to the top right. When a standard parser looks at that same PDF, it often reads straight across the page. The result is a scrambled word soup. A language model fed this broken text will hallucinate confidently, combining the methodology section with the conclusion.
The industry response to scrambled layouts has been brute force. Tools like MinerU push entire documents through massive Vision-Language Models. This works, but it imposes a massive GPU tax. Processing a thousand-page archive becomes a costly, slow operation.
The Triage: Surgical AI vs. Brute Force
OpenDataLoader takes a different architectural path. Written primarily in Java, its core engine treats PDF parsing as an economic optimization problem. The core solution is a hybrid architecture anchored by a component called the TriageProcessor.
Instead of sending every page to a neural network, the engine analyzes the geometry of each page first. It looks for signals like aligned short lines, grid patterns, and image aspect ratios. If the page is a standard single-column text document, it stays on the fast, local Java path. If the engine detects a complex borderless table or dense mathematical formulas, it routes that specific page to an AI backend like Docling.
This conservative routing strategy minimizes false negatives. If the Java engine is unsure about a layout, it defaults to the AI backend to prevent data loss. The result is an engine that processes 90 percent of a standard document at CPU speeds, only calling for expensive AI backup when absolutely necessary.
XY-Cut++: Solving the Gutter
When a page stays on the local Java path, it relies on a deterministic heuristic algorithm called XY-Cut++. This is a recursive partitioning technique designed specifically to solve the multi-column reading order problem.
The algorithm works by finding the "gutters" on a page. It makes a horizontal cut to separate the header, then a vertical cut to separate the two columns, and then horizontal cuts within those columns to isolate paragraphs. By recursively slicing the page into smaller bounding boxes, the engine constructs a mathematically rigorous reading order without needing a neural network to "see" the page.
Beyond RAG: The Accessibility Mandate
High-fidelity data extraction is only half the project's mandate. OpenDataLoader was built with a secondary goal that most AI tools ignore completely: enterprise compliance.
By collaborating with the PDF Association, the Hancom team engineered the parser to output Tagged PDFs (PDF/UA compliance). This standard ensures that screen readers can accurately voice the document to visually impaired users. It translates the internal semantic tree (headings, paragraphs, lists) into the strict XML-like structure required by accessibility laws.
Benchmarking the Hybrid Tax
The architectural choices inside OpenDataLoader translate directly into performance. By keeping the bulk of document processing on the CPU, the parser achieves a speed of 0.05 seconds per page for standard layouts.
While heavyweight models excel at niche scientific formulas, the hybrid approach proves more practical for general enterprise workloads.
| Project | Primary Hardware | Core Approach | Key Output |
|---|---|---|---|
| OpenDataLoader PDF | CPU (GPU optional) | Deterministic + AI Triage | JSON, Tagged PDF, Markdown |
| MinerU | GPU Required | Vision-Language Models | Markdown, LaTeX |
| Docling | CPU/GPU | Specialized Layout Models | JSON, Markdown |
| Marker | GPU Recommended | AI Layout Pipeline | Markdown |
The Corporate Steward
OpenDataLoader was released in early 2026 under the Apache 2.0 license by Hancom, a major South Korean software firm. This corporate backing provides a level of stability rare in hobbyist AI projects.
The library features comprehensive Checkstyle configurations, robust GitHub Actions for continuous benchmarking, and SDK wrappers for Python and Node.js. It is built to run reliably in high-concurrency environments, utilizing thread-local storage to prevent state leakage across parallel batch jobs. For developers building the next generation of knowledge bases, the end of the GPU tax is finally here.
Sources: