geo-optimizer-skill: GEO Optimizer: The Open-Source Lighthouse for AI Citability
It audits robots.txt, llms.txt, schema, and brand signals, then turns research on generative engine optimization into a tool an AI agent can actually use.
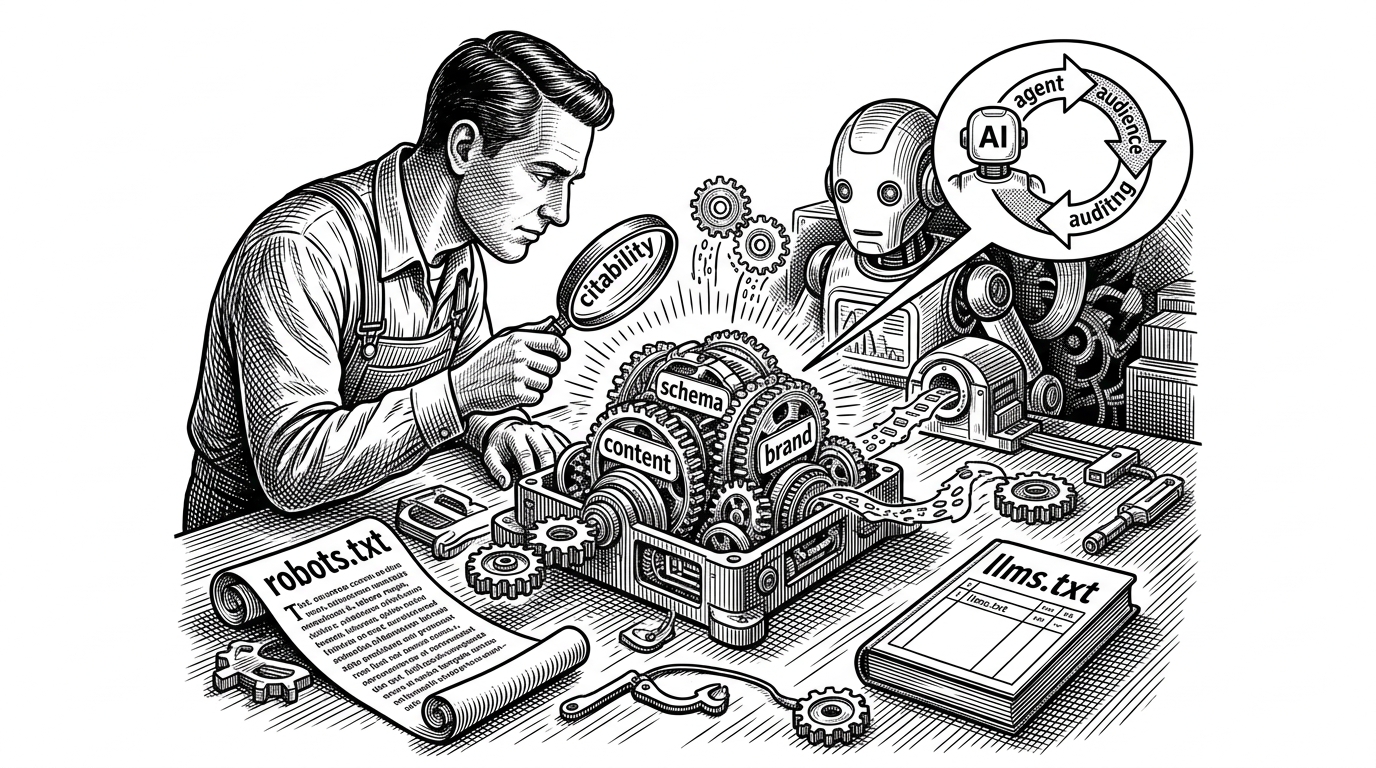
- GEO Optimizer turns AI citability into a measurable audit, so the question shifts from "Can this page rank?" to "Can an AI system trust and cite it?"
- Its scoring model is more nuanced than a checklist because it grades schema richness, discovery signals, and brand coherence instead of only detecting whether they exist.
- The plugin architecture and MCP server make the project feel like infrastructure, since the same engine can run in a CLI, in automation, or inside an agent workflow.
- Compared with commercial GEO dashboards, this repo is narrower and more actionable: it is built to diagnose and fix technical readiness, not just report visibility.
AI Search Is Not a Ranking Problem
Traditional SEO asks where a page appears in a results list. GEO Optimizer starts from a different question: will an LLM parse this page, trust it, and cite it inside an answer? That shift matters because the surface area is no longer a SERP. It is an AI system with its own retrieval, summarization, and citation habits.
The first open-source GEO audit and optimization engine. Based on the Princeton KDD 2024 research paper + AutoGEO ICLR 2026 methods.
That framing is the project’s real contribution. It does not treat AI visibility as a vague brand problem. It treats it as an engineering problem with inputs, checks, weighted scores, and outputs you can act on.
What GEO Optimizer Actually Does
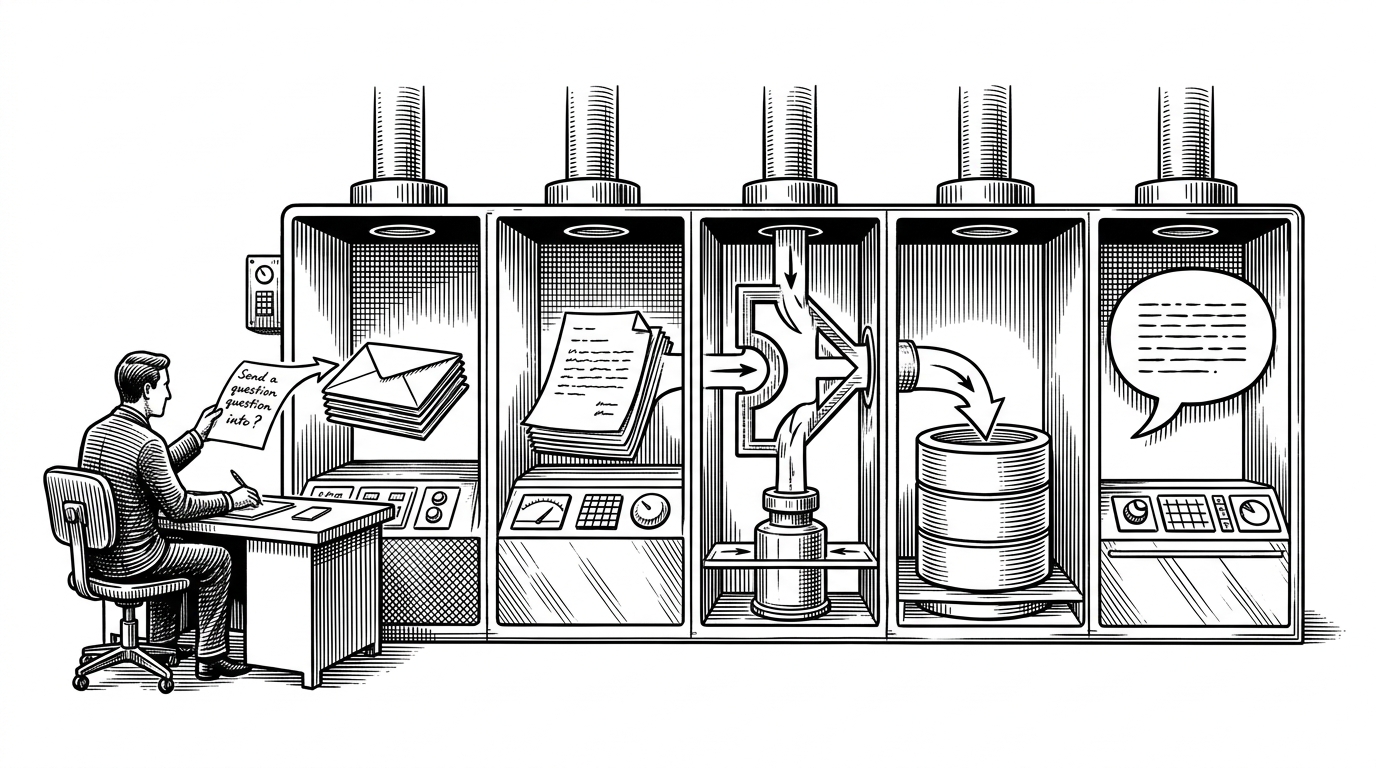
The repository packages research on generative engine optimization into a practical audit stack. It checks whether a site is legible to machine readers across robots.txt, llms.txt, structured data, meta tags, content depth, AI-specific signals, discovery surfaces, and brand coherence.
The Scoring Engine Turns AI Readiness Into Numbers
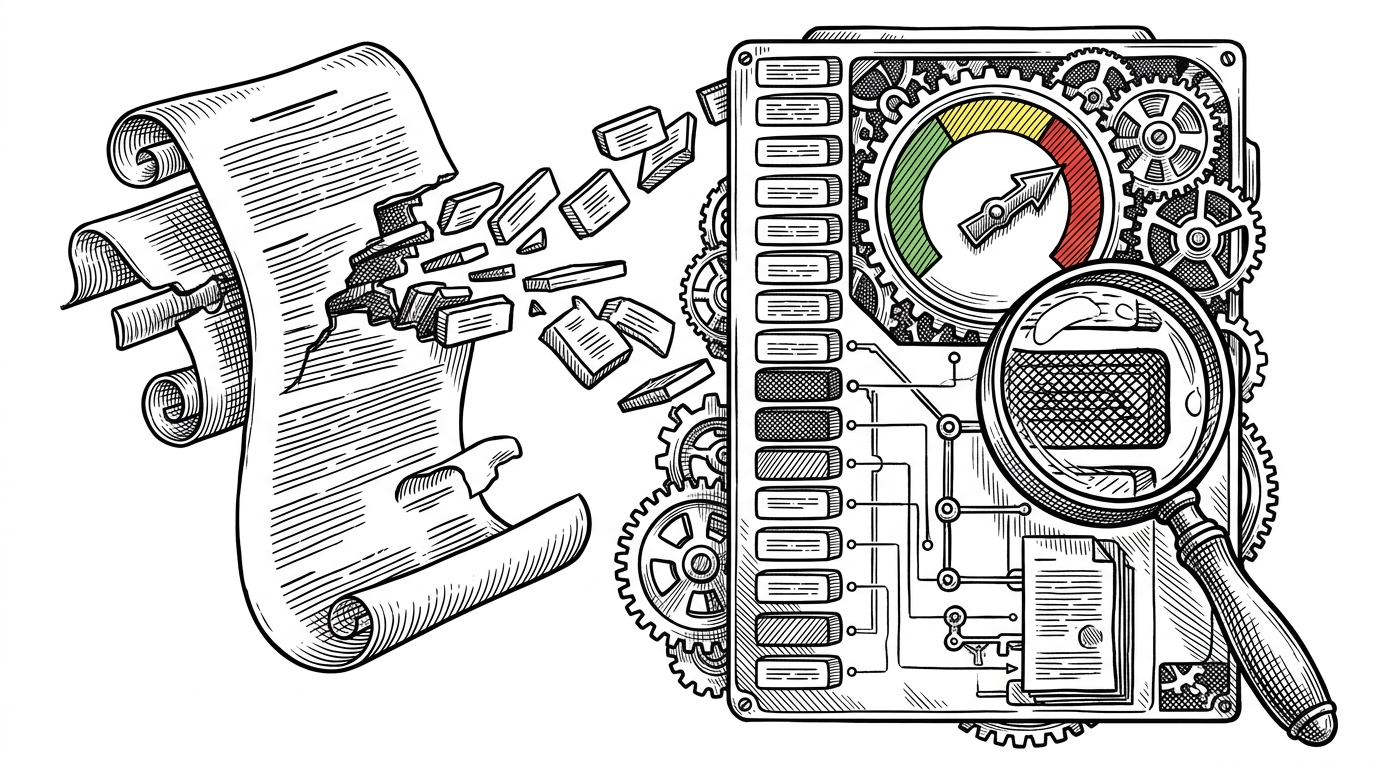
The heart of the system lives in scoring.py. Its model breaks AI readiness into weighted categories, which is important because a page can be partially compliant and still be weak at being cited.
That is where schema richness becomes a useful distinction. A site that merely has JSON-LD is not the same as a site that expresses entities, relationships, and context in ways an LLM can actually use. GEO Optimizer scores the second case higher because it is closer to machine-readable meaning, not just markup presence.
# Conceptual shape of the scoring model
score = {
    "robots": ...,
    "llms": ...,
    "schema": {
        "presence": ...,
        "richness": ...
    },
    "meta": ...,
    "content": ...,
    "signals": ...,
    "ai_discovery": ...,
    "brand_entity": ...
}

final_score = weighted_sum(score)