Auto-Schema-Pipeline: The Project That Turns Unknown CSVs Into a Safe, Self-Explaining Analytics Loop
A zero-config Python pipeline that infers schema, asks Gemini to invent analysis questions, validates the SQL, and outputs charts and reports without manual boilerplate.
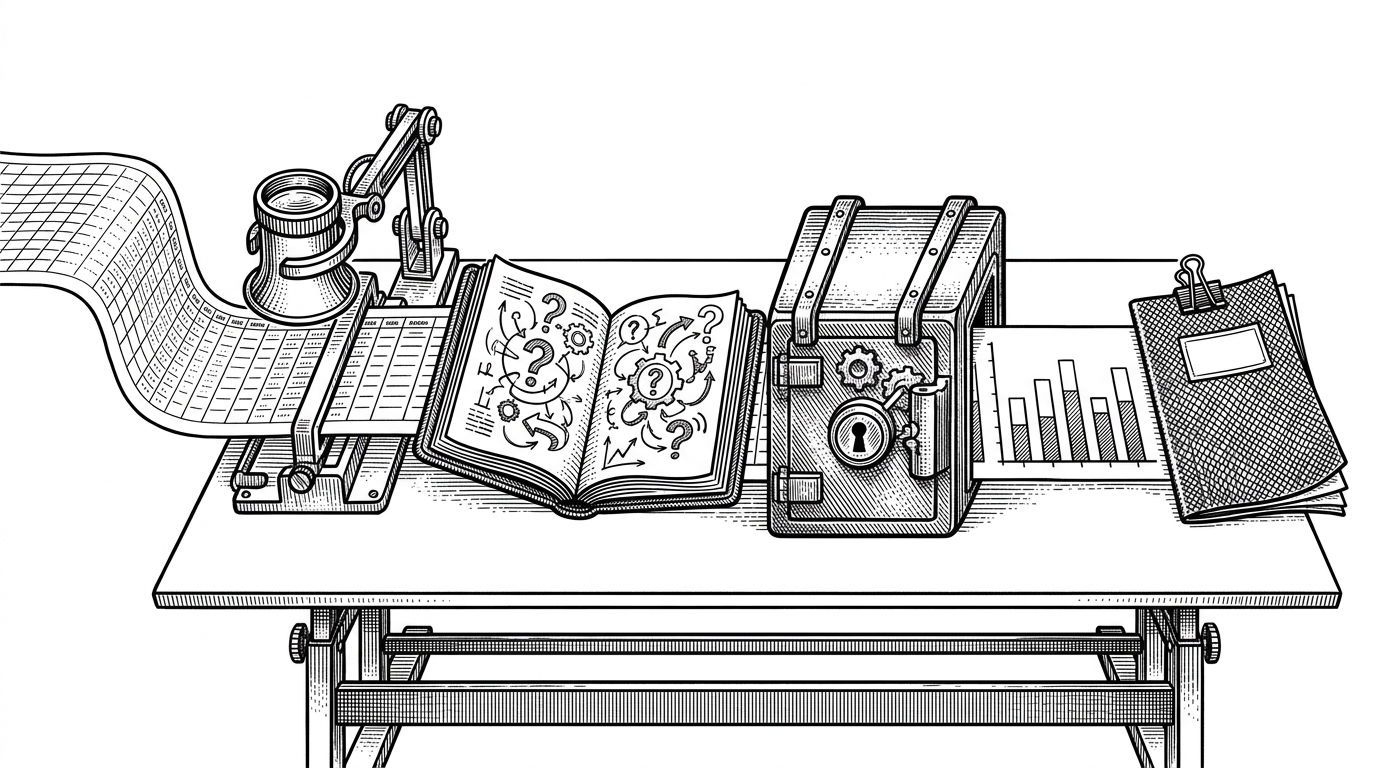
- Auto-Schema-Pipeline is most interesting as a schema-first analysis loop that invents questions from data structure instead of waiting for a human prompt.
- Its real contribution is orchestration, not novelty for its own sake: schema inference, AI question generation, SQL validation, and charting are chained into one controlled workflow.
- The safety layer is useful but limited, because it filters AI output with simple guards rather than proving SQL is truly safe.
- The project feels like a compact blueprint for cold-start exploratory analysis, especially when the goal is to turn an unknown CSV into an immediate report.
The Pipeline That Starts With the Schema, Not the Prompt
Most AI data tools begin with a question. This one begins with a file and asks what questions are even worth asking. That shift matters, because the hardest part of cold-start analysis is not query writing. It is deciding where to look first.
Auto-Schema-Pipeline reads an unknown CSV, infers a relational schema, asks Gemini to propose analysis questions from that schema, then validates and executes only safe SQL before turning the result into charts and a report. That makes it less like a chatbot wrapper and more like a controlled exploratory machine.
Why Cold-Start EDA Is the Real Problem
The first hour of data work is rarely glamorous. Someone opens a file, guesses types, checks for missing values, creates a table, tests a few queries, and then makes the first chart. Only after that does the real analysis begin.
This project automates that boring first pass. It is aimed at the moment when the dataset is unfamiliar, the schema is not trusted, and the user wants a useful readout fast. In that sense, the value is not just speed. It is reducing the cognitive cost of starting.
How Schema Inference Makes the AI Less Dumb
The most important design choice sits in src/schema_detector.py. Pandas dtypes are mapped to PostgreSQL types, so the model is not reasoning over raw text alone. It is reasoning over a typed structure, which gives the downstream SQL a much better chance of being numerically and temporally correct.
That detail changes the whole system. A date column can become a time series. A numeric column can support averages, histograms, and grouping. Without type inference, the model is guessing in the dark. With it, the pipeline has a usable model of the table before Gemini ever sees a prompt.
| Layer | Input | Output | Why it matters |
|---|---|---|---|
| Manual CSV analysis | Raw file and human attention | Ad hoc findings | Flexible, but slow to start |
| Text-to-SQL | Human question | One query | Useful only after you already know what to ask |
| Auto-viz | A result set | A chart | Reactive, not exploratory |
| Auto-Schema-Pipeline | Schema plus sample rows | Questions, SQL, charts, and report | Turns structure into a guided analysis loop |
The Safety Gate Between Gemini and the Database
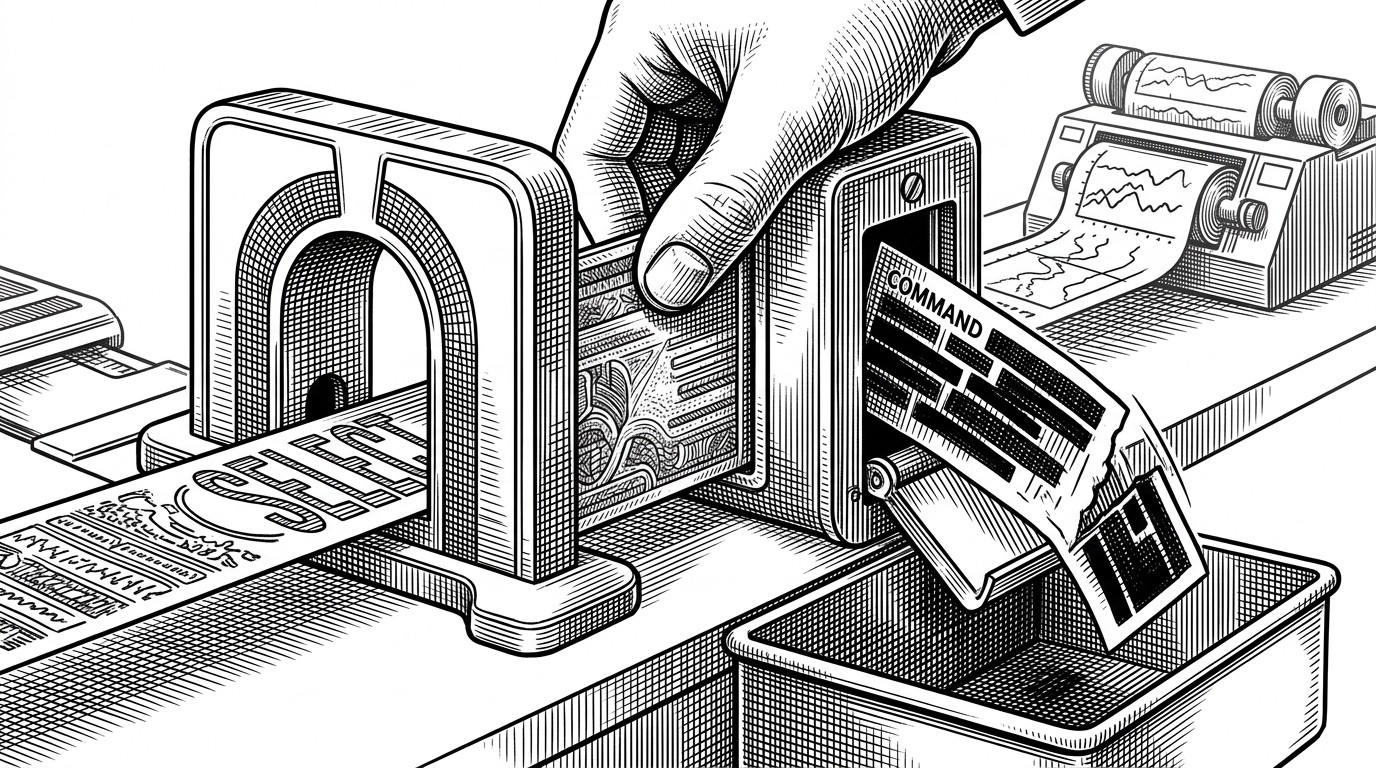
The query path runs through src/gemini.py and src/validate_query.py. Gemini is asked to produce structured output, but the validator decides whether that output is allowed to touch the database at all.
The checks are simple and useful. The query must be a SELECT statement. It must contain the expected table name. It must reference at least one known column from the schema. That is enough to stop obvious damage and keep the workflow focused on analysis.
It is also not full SQL security. String matching can be fooled, and prompt injection is still a real concern. The article's useful claim is narrower: this is a practical guardrail for a local or sandboxed analytics loop, not a proof of safety for arbitrary untrusted execution.
Why the Visualization Step Matters More Than It Looks
The project becomes much more persuasive once the query result turns into a chart. That happens in src/visualise.py, where the shape of the output decides the chart type. Time data becomes a line chart. Numeric lists become histograms. Filenames are slugified so the output stays traceable.
That is the difference between a query runner and an exploratory system. The tool does not stop at returning rows. It interprets the result, chooses an appropriate visual form, and packages the output into something a human can scan quickly.
The Orchestrator Is the Real Product
The center of gravity is main.py and its run_pipeline pattern. Every run gets a run_id, the process logs failures as well as successes, and the system keeps state across a messy multi-step flow. That is what makes the project feel more like a product than a notebook.
This matters because the pipeline has several failure points. Data can be malformed. Gemini can drift. SQL can be rejected. Visualization can fail. By preserving run state, the orchestrator gives the operator a way to inspect what happened instead of losing the trail.
| Approach | Strength | Weakness |
|---|---|---|
| Manual analysis | Maximum control | Slow and repetitive |
| Conventional ETL | Reliable structure | Still expects human-defined logic |
| Full BI suite | Polished reporting | Heavyweight for ad hoc exploration |
| Auto-Schema-Pipeline | Fast cold-start analysis | Needs stronger hardening for high-trust use |
What It Is Not
This is not a generic ETL platform. It is not a full BI tool. It is not a broad autonomous agent. It is a constrained pipeline with one sharp job: turn unknown tabular data into immediate exploratory output.
That constraint is the point. The project stays legible because it narrows the problem instead of trying to solve data operations in general. The result is a small but coherent blueprint for schema-first autonomous EDA.
Where It Fits
The sweet spot is internal tools, prototype data products, analyst workflows, and demo-driven exploration. It is especially useful when speed matters and the goal is to get from raw file to something interpretable without hand-building the plumbing every time.
The limit is trust. For production use, it would need stronger SQL hardening, clearer lineage, better test coverage, and tighter execution controls. As a pattern, though, it is compelling: infer the shape, ask the questions, verify the query, then show the result.