The Architecture of Nothing: Inside shobhit99/testrepo
How a non-functional script exposes the mechanical biases of GitHub's massive repository classification engine.
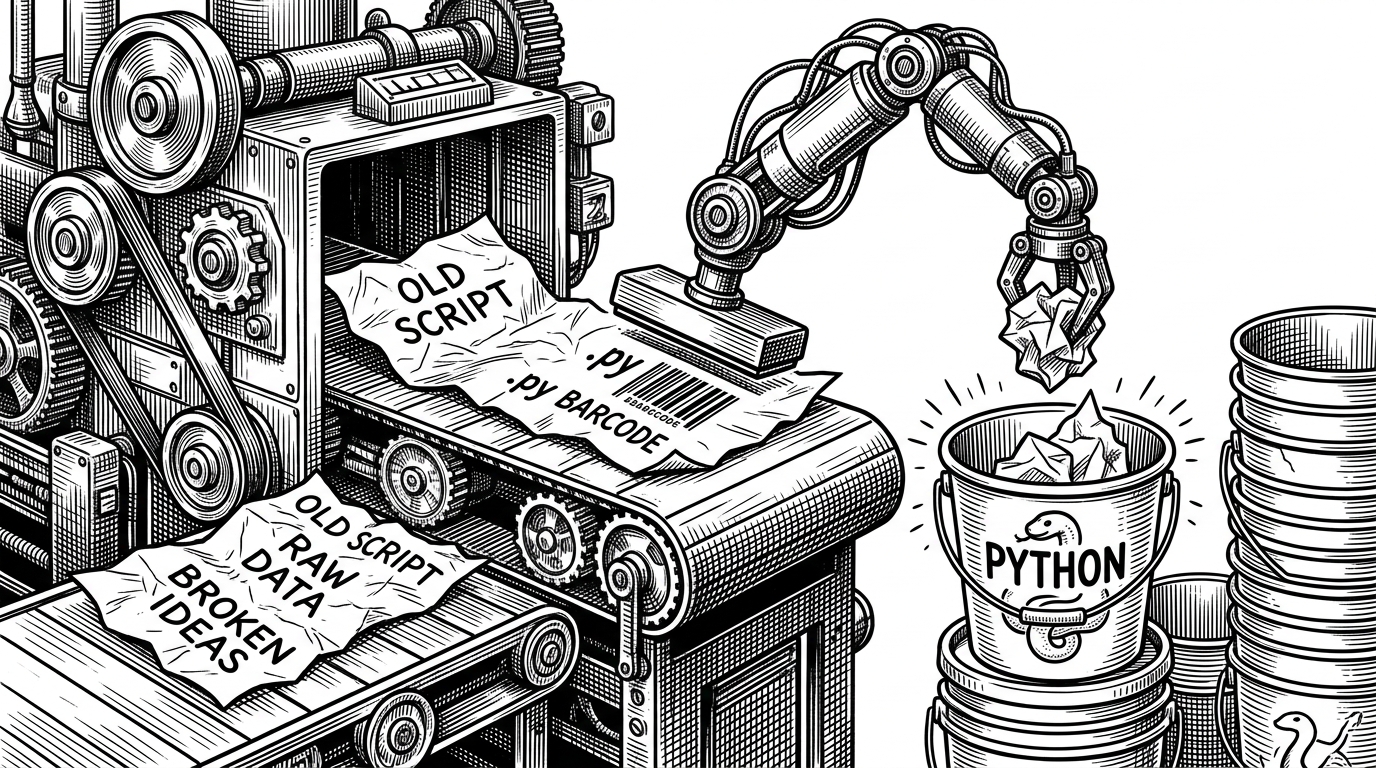
- GitHub's Linguist engine prioritizes file extensions over AST parsing to manage planetary-scale compute costs.
- The shobhit99/testrepo project perfectly exploits this heuristic, achieving a 100% Python classification with zero lines of valid code.
- Millions of similar 'null repositories' form the dark matter of open source, serving as essential sandboxes for developers learning version control.
The 100 Percent Python Illusion
According to the pristine purple bar rendering in the GitHub UI, shobhit99/testrepo is a Python codebase. It is 100% Python. The classification engine is confident in this assertion. Yet, a closer inspection of the repository reveals a structural paradox: there is no Python code.
The repository contains exactly one functional file, named test.py. Inside that file is a single string of plain English text. Any standard Python interpreter encountering this file will immediately throw a SyntaxError. The file lacks the foundational grammar of the language—no print() statements, no variable assignments, no execution logic. It is, functionally, plain text.
This is testThis contradiction between the platform's metadata and the repository's execution reality is not a bug. It is a feature of how planetary-scale code analysis works, and testrepo serves as a perfect, unintentional stress test of that system.
Bypassing the Parser
To understand why GitHub classifies a plain text file as Python, we have to look at Linguist, the open-source library that powers GitHub's language statistics. When a developer pushes a commit, Linguist analyzes the delta to update the repository's language breakdown.
At GitHub's scale—processing millions of commits per day—running a full Abstract Syntax Tree (AST) parser on every file to verify its structural validity would be computationally ruinous. The compute cost of tokenizing and parsing every line of code pushed to the platform is simply too high. Instead, Linguist relies on a cascade of heuristics.
The most heavily weighted heuristic in this cascade is the file extension. If a file ends in .py, Linguist assumes it is Python. If it ends in .rb, it assumes Ruby. While Linguist does employ Bayesian classifiers and heuristics to disambiguate common extensions (like .m for Objective-C vs. MATLAB), a completely unambiguous extension like .py bypasses deeper semantic analysis. testrepo exploits this shortcut perfectly, wearing the metadata uniform of a Python script without possessing any of its substance.
Anatomy of the Digital Fossil
Beyond the test.py file, the repository contains only a README.md. This document is equally minimalist, containing only a redundant double-header.
This specific artifact—the redundant header—is a digital fossil. It is the footprint of an automated repository creation script (which generates the first header) colliding with a manual user edit (who types the second header, assuming the file is empty). It represents the 'Hello World' of version control management, rather than the 'Hello World' of programming.
The Dark Matter of Open Source
When we discuss open-source software, the conversation inevitably gravitates toward massive, load-bearing frameworks like React, Kubernetes, or testing suites like Pytest and Jest. These projects are highly visible, heavily starred, and deeply integrated into the global software supply chain.
But these behemoths sit atop a vast ocean of invisible infrastructure. There are millions of repositories named test, testrepo, or hello-world on GitHub. They have zero stars, zero forks, and exist only to provide the necessary scaffolding for a developer learning to bridge their local environment with the cloud. They are the dark matter of the open-source ecosystem—serving zero functional purpose in production, but holding the entire learning structure together.