core-team-issues: The GitHub repo that turns issue triage into an AI control plane
Twenty split its core-team workflow into a separate repo, then wired @claude into a GitHub Action that dispatches work back to the main codebase.
We're building the first open-source alternative to Salesforce.
- core-team-issues is a clean-room router for the Twenty core team, not a public-facing backlog.
- Its @claude workflow converts issue activity into a structured dispatch event that the main repo can consume.
- That split keeps the main codebase quieter, but it also makes permissions and cross-repo dispatch part of the operating model.
- Twenty is treating issue management as infrastructure, which is what makes the repo unusually revealing.
This repository does not hold product code. It holds decisions. twentyhq/core-team-issues exists so the people building Twenty can keep high-signal work away from the churn of the main CRM repo, then route certain issues straight into an AI-assisted workflow.
A clean room for the people who build the product
Open-source CRMs accumulate two kinds of noise at once: public requests and internal implementation debate. A separate issue repo compresses the second kind into one place, where core maintainers can move faster without dragging every architectural argument through the same backlog that handles user-facing work. That is not just tidier. It makes the repo legible enough for an agent to act on it.
That ambition explains why this tiny repo matters. If Twenty wants to feel like a serious alternative to Salesforce, it needs more than a modern UI and a good data model. It needs an operating model that lets the team move work, not just store it.
How @claude becomes a workflow, not a novelty
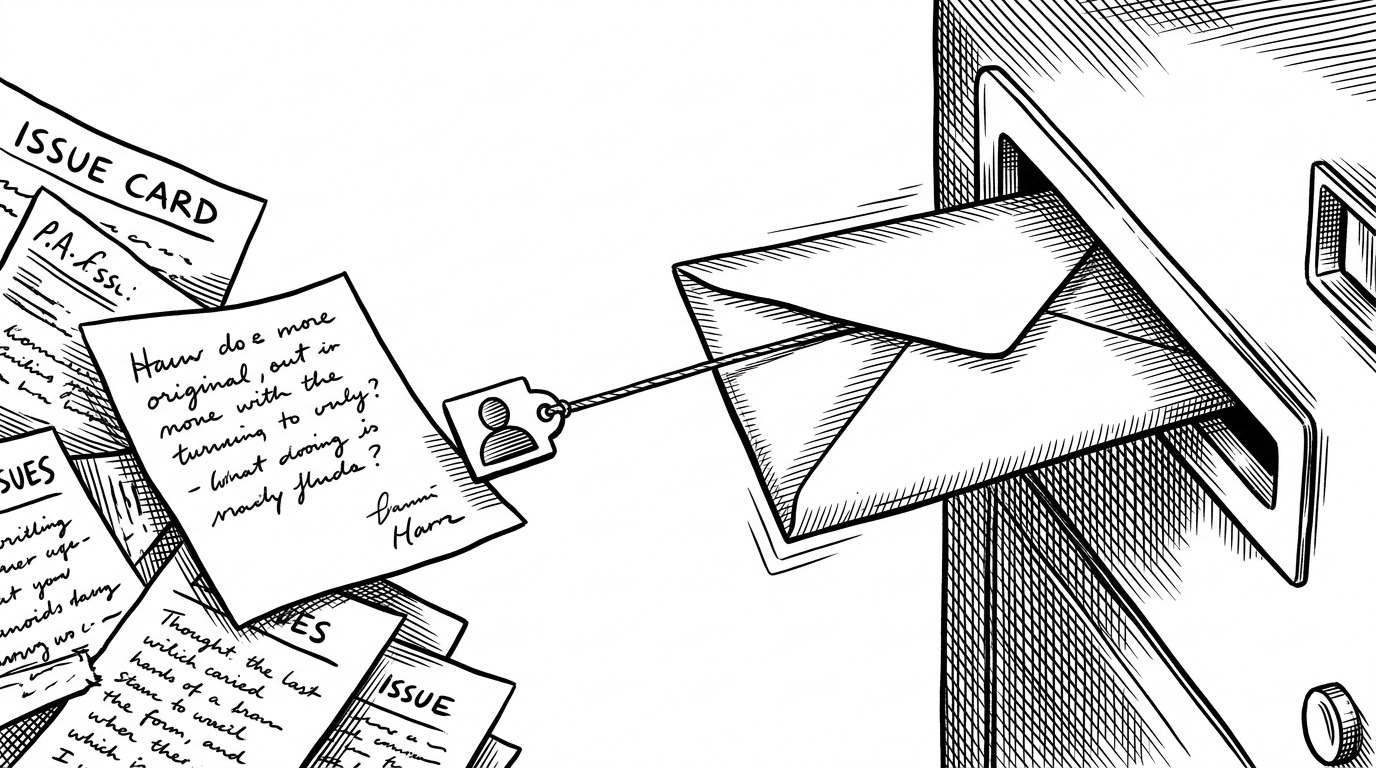
The workflow is almost austere. GitHub watches issue events, a script filters for explicit @claude mentions, and the result is sent as a normalized payload to the main Twenty repository. No separate server. No custom queue. Just GitHub Actions turning a mention into a packet.
The important detail is the normalization step. The workflow strips a noisy human conversation down to the fields a downstream agent actually needs: issue number, issue URL, body, sender, and repository name. That is what makes the handoff reliable. The AI does not have to guess what the issue meant because the workflow has already turned context into structure.
Why assignment matters more than a mention
The most revealing trigger is not a comment. It is assignment. When a task is assigned, the workflow can forward the sender alongside the issue itself, which means the AI is being placed into an explicit chain of accountability rather than a vague chat thread. That is a small design choice with a large cultural effect.
I think you will be able to set up a custom dashboard by the end of the year with such information by using custom layouts and groupBy api which @etiennejouan is working on would allow such a thing ?
That issue thread shows the repo doing real product work, not just meta-work about the repo itself. It is where the team hashes out feature shape, API direction, and implementation details that would otherwise get buried inside a larger backlog. The separate repo keeps those decisions sharp.
Why this beats one monolithic issue tracker
| Pattern | How work enters | What it optimizes for |
|---|---|---|
| Issues in the main repo | Every discussion lands where the code lives. | Simplicity, but higher noise. |
| core-team-issues | Core work lands in a separate issue router. | Signal, accountability, and AI dispatch. |
| External bot or service | Work leaves GitHub and enters another system. | Flexibility, but more moving parts. |
The tradeoff is obvious. Twenty pays for the clean split with an extra hop and a second permission boundary. But that friction buys isolation, and isolation buys speed when the team wants to iterate on agentic workflows without turning the main codebase into a pilot project.