LinkPulse: The Redirect Engine That Refuses to Wait
A deep dive into the shortlink stack that uses Bloom filters, Redis, queues, and fail-open rate limiting to make every click feel instant.
The Click Should Not Wait
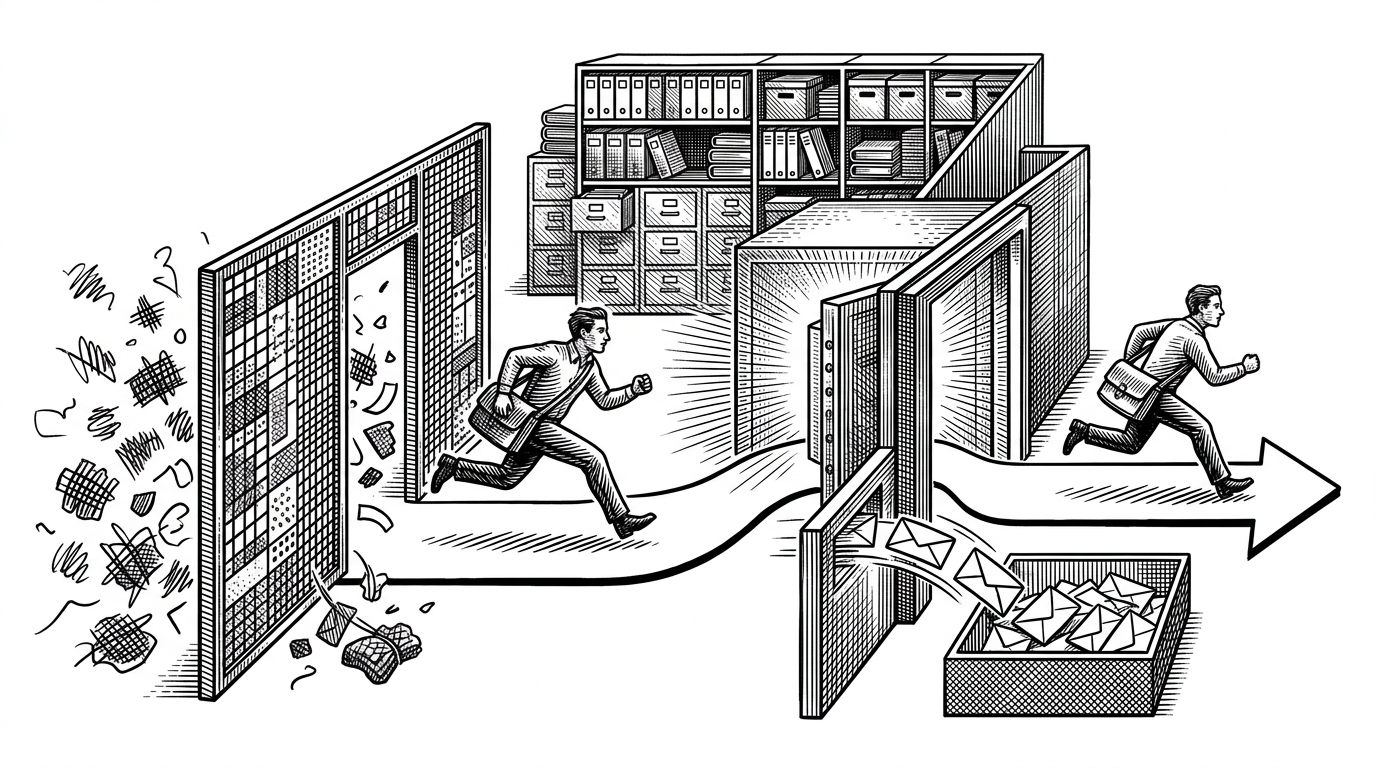
A shortlink service has one job that cannot slip: turn a request into a destination. LinkPulse treats that redirect as sacred, then refuses to let analytics, persistence, or dashboards sit in the middle of the click path.
That choice changes the shape of the entire repo. The system is not trying to be elegant in the abstract. It is trying to be fast when traffic is noisy, honest when metrics matter, and resilient when Redis or MongoDB is having a bad day.
What LinkPulse Is Actually Optimizing For
LinkPulse is not just optimizing for short URLs. It is optimizing for short URLs under stress, with enough analytics and guardrails to make the service useful beyond a toy demo.
The repository reads like a production system because it solves production problems: hot-path latency, cache misses, abusive traffic, async persistence, and live operational visibility. The interesting part is not any one feature. It is the way the parts are ordered.
| System | Redirect latency posture | Analytics handling | Failure behavior | Best use case |
|---|---|---|---|---|
| Naive shortener | Everything happens inline | Basic logging, if any | Redirect slows down when any dependency slows down | Tiny demos and prototypes |
| LinkPulse | Redirect is first and protected | Queued after the click returns | Fail-open where availability matters | Self-hosted shortlinks with real traffic |
| Analytics-heavy platform | Reporting first, request path often fuller | Rich and immediate | More coupling between insight and speed | Marketing teams that prize dashboards over raw latency |
The Critical Path: Bloom Filter, Cache, Database
The request path in redirect.js is layered on purpose. A Bloom filter rejects obvious misses early, Redis serves the hot path, MongoDB fills the gaps, and the cache gets repopulated so the next request is cheaper.
That is the whole trick: spend the smallest possible amount of work on the hottest path, then repair the cache and capture analytics after the redirect has already been sent.
// Conceptual flow from the repo analysis
if (!bloomFilter.mightExist(code)) {
  return notFound();
}

const cached = await cacheService.getCachedUrl(code);
if (cached) {
  redirect(cached);
  queueAnalytics(code);
  return;
}

const link = await Link.findOne({ code });
if (!link) return notFound();

await cacheService.cacheUrl(code, link.destinationUrl);
redirect(link.destinationUrl);
queueAnalytics(code);
Why the Bloom Filter Matters
The Bloom filter is not there for novelty. It is there to reject junk without paying the cost of a database lookup. That matters when a redirect endpoint is exposed to high volumes of random codes, scanner traffic, or accidental mistypes.
Why Analytics Never Get to Block the Redirect
The most important philosophical move in LinkPulse is also the simplest: the service sends the redirect first, then hands analytics off to a queue. That keeps bookkeeping from leaking into user latency.
This is where the repo stops looking like a CRUD app and starts looking like a system. The redirect is a response. Analytics are a job. Those are different things, and LinkPulse keeps them different on purpose.
The worker later persists click data, updates counters, and feeds the dashboard. The request thread never waits for that work to finish, which is exactly what a redirect service should want.
The Rate Limiter That Trusts Redis, But Not Too Much
LinkPulse’s rate limiter uses Redis and Lua so the check and decrement happen atomically. That is a small implementation detail with a big consequence: it avoids the race conditions that appear when several app instances try to police the same key at once.
The more interesting decision is the fail-open behavior. If the limiter infrastructure breaks, the system chooses availability over strict enforcement. For a redirect service, that is a sensible trade. Blocking legitimate traffic because the limiter is sick is worse than letting a few requests through.
Generating illustration...
| Approach | Why it works | Where it hurts |
|---|---|---|
| Standard middleware rate limiting | Simple to add | Can race under distributed load |
| Redis Lua token bucket | Atomic within Redis | Depends on Redis availability |
| Fail-closed limiter | Strict enforcement | Can take the redirect down with it |
| LinkPulse fail-open limiter | Keeps redirects flowing | Allows some traffic during limiter failures |
Real-Time Dashboards Without Real-Time Pain
LinkPulse wants the dashboard to feel live without making the redirect pay for it. The answer is a buffer-and-flush pattern: Redis holds the newest counters and recent clicks, then a worker persists the longer history later.
That split gives the frontend immediate visibility and the backend time to do durable work. In practice, it means the product can show activity quickly without forcing every click to wait for storage writes.
It is a clean example of a deeper pattern in the repo. Anything that helps humans see what is happening should be fast. Anything that makes the data durable can happen after the fact.
A/B Testing Changes the Rules
A/B links are a small feature with a big architectural consequence. Once a link’s destination depends on weighting, the service can no longer treat the result as a normal cacheable constant in the same way it does for ordinary redirects.
That is why LinkPulse disables caching for A/B routes. The point of the feature is traffic shaping, not just destination lookup. If you cache the answer too aggressively, you flatten the distribution and undermine the experiment.
| Routing mode | Caching behavior | Primary risk | Why it matters |
|---|---|---|---|
| Normal link | Cache after first lookup | Stale lookup if invalidation is sloppy | Fast repeated redirects |
| A/B link | Do not cache the same way | Distribution drift | Experiment fidelity |
| Weighted test with analytics | Track outcomes separately | More moving parts | Useful signal for marketers and product teams |
The code path here is less about pure speed and more about keeping behavior faithful. Sometimes the right optimization is to refuse an optimization that would distort the result.
How It Compares to a Naive Shortener
A naive shortener tends to do too much in one place. It looks up the URL, writes analytics, maybe updates counters, maybe logs abuse signals, and only then returns the redirect. That is tidy on paper and messy under load.
LinkPulse breaks that habit. It uses the cheapest reliable check first, caches aggressively, pushes noncritical work onto queues, and treats failure as something to route around rather than pretend away.
| System | Redirect path | Analytics path | Rate limiting | Operational stance |
|---|---|---|---|---|
| Naive shortener | Single inline flow | Inline or minimal | Usually bolted on | Works until traffic or dependencies grow |
| LinkPulse | Layered fast path | Asynchronous queue and worker | Atomic Redis Lua with fail-open fallback | Designed for resilience and throughput |
| Traditional analytics stack | Often heavier request path | Reporting-first | Varies widely | Strong insight, weaker redirect purity |
What This Repo Gets Right
The strongest thing about LinkPulse is not the number of features. It is the discipline behind them. Every major choice protects the same promise: the redirect should feel instant, even when the rest of the system is busy, noisy, or partially broken.
That is a mature instinct. Plenty of projects add analytics, dashboards, and anti-abuse logic. Fewer projects arrange those features so they never get between the user and the destination.