The Index Predictor: How `ai-fitness-planner` Turns a Decision Tree Into a Personalized Workout Engine
A small Flask and React stack uses row indexes, CSV mappings, and a simple UI parser to turn structured user inputs into a ready-made fitness plan.
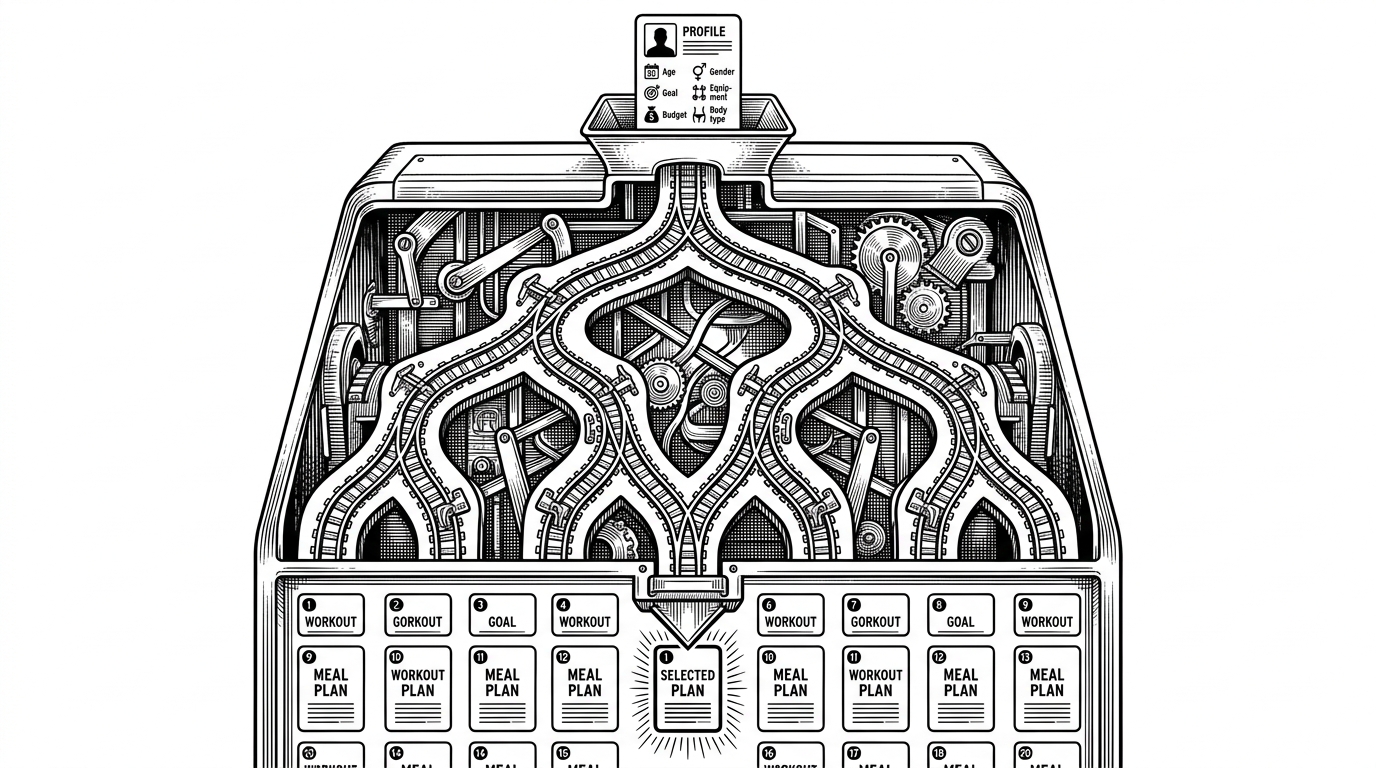
- This repo repurposes a decision tree as a row selector, so the model behaves more like a recommendation lookup engine than a normal classifier.
- The project is built around a fixed CSV schema, which keeps the backend predictable and makes the ML layer easy to reason about.
- The frontend does real interpretation work by turning semi-structured plan text into readable color-coded cards.
- The stack favors simplicity and operational discipline over generative flexibility, which is exactly why it feels useful.
The classifier that does not classify
The clever move in this repo is not that it predicts fitness plans. It is that it predicts a CSV row index. In `train_model.py`, the target is essentially the dataset position itself, which turns the decision tree into a routing system for a curated plan library.
That changes the job of machine learning. The model is not asked to invent a regimen or label a person. It is asked to find the closest fit among known rows, then hand that row to the rest of the stack.
# train_model.py
X = df[["age", "gender", "goal", "equipment", "budget"]]
y = df.index

model = DecisionTreeClassifier(max_depth=12)
model.fit(X_encoded, y)
Built from a spreadsheet, not a model zoo
The repository feels more like a data product than a research project. The core asset is a CSV named `workout_diet_dataset.csv`, and the surrounding code exists to encode its fields, train a small tree, and retrieve the matching row with minimal ceremony.
That simplicity is the point. A fixed schema makes the system legible. If the inputs are age, gender, goal, equipment, budget, and body type, the outputs can be a stable set of meals and workouts without inventing a new ontology for every request.
- The dataset is the real product surface, not a prompt template.
- Categorical mappings keep the backend and inference path aligned.
- The model can stay small because the plan library is already curated.
How the row lookup works end to end
The pipeline is straightforward. `train_model.py` encodes the structured inputs, trains a decision tree, and persists the model artifact. `app.py` receives JSON, applies the same feature mappings, calls `predict`, and then fetches the row that corresponds to the returned index.
That row then becomes the fitness plan. The API also logs requests into SQLite, which adds a basic audit trail and makes the app look more operationally serious than a throwaway demo.
# app.py
payload = request.get_json()
encoded = encode_features(payload)
row_index = model.predict([encoded])[0]
plan = dataset.iloc[row_index]
log_to_sqlite(payload, row_index, plan)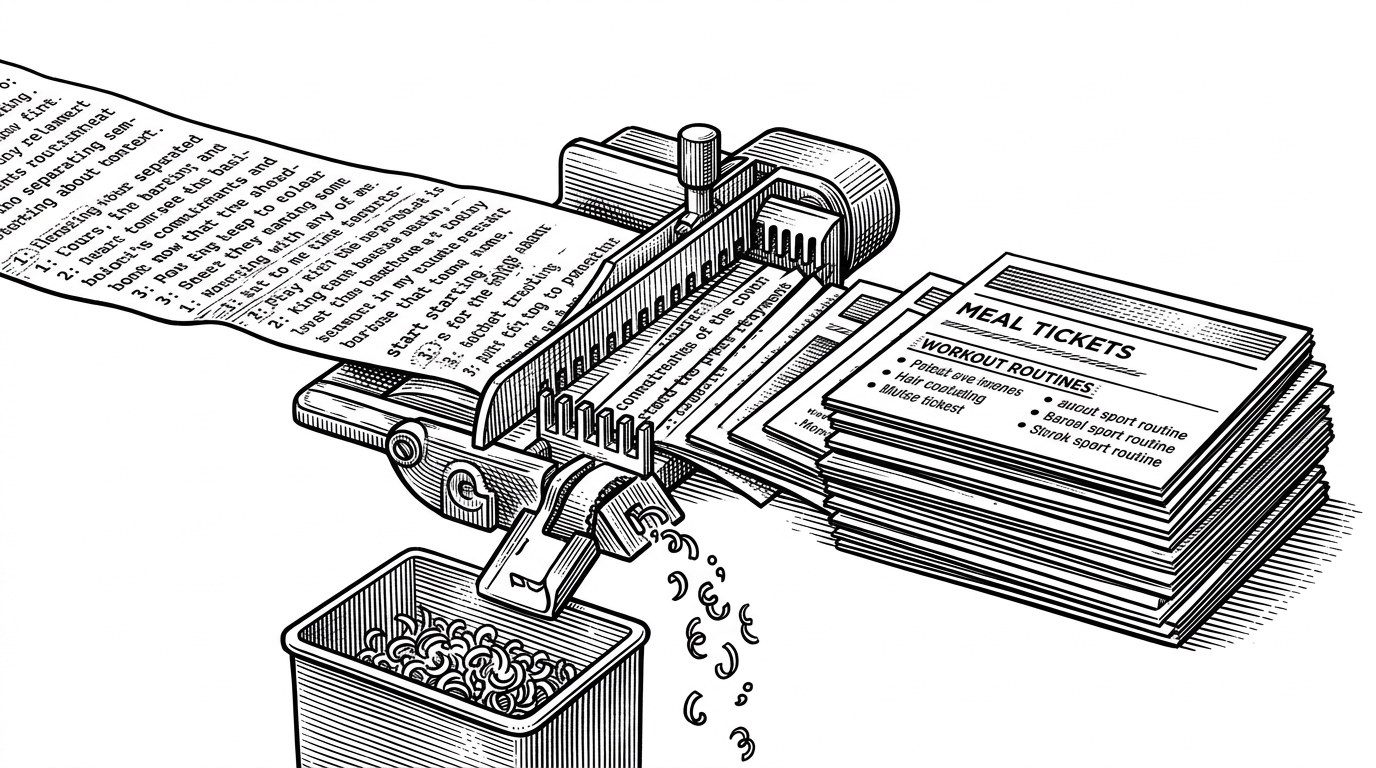
Why the frontend matters more than it looks
The React app is doing real interpretation work. It manages a multi-step state flow, then parses the plan string into a more usable layout. That is not cosmetic polish. It is the difference between a blob of output and a readable schedule.
The color mapping matters too. By assigning stable visual treatments to meal and workout blocks, the UI makes dense output feel structured without needing a heavier backend format.
A lightweight production stack with real deployment intent
| Dimension | This repo | Conventional recommender | LLM planner |
|---|---|---|---|
| Input shape | Structured profile fields | Structured profile fields plus learned score features | Prompt plus context |
| Output | Dataset row index | Label or ranked list | Generated plan text |
| Latency | Low | Low to moderate | Higher |
| Maintenance | Simple CSV and mappings | Model plus mapping layer | Prompting, guardrails, evals |
| Failure mode | Wrong row selection | Wrong ranking or label | Hallucinated or inconsistent plans |
| Operational footprint | Small | Medium | Large |
The stack choice signals intent. Waitress is used for serving, SQLite handles persistence, and the backend is separate from the frontend. That is what a deployable prototype looks like when someone expects it to run outside their editor.
What this project is, and what it is not
This is not a dynamic coach. It is not a medical system. It is not trying to infer meaning from free text or reason across a giant catalog of possible plans.
It is a disciplined shortcut. By keeping the dataset curated and the model small, the repo delivers a useful recommendation flow with a very light operational burden. That is the real lesson: sometimes the smartest AI product is the one that stops short of generation.
| Approach | Strength | Trade-off |
|---|---|---|
| Index-as-label tree | Predictable, cheap, easy to ship | Limited adaptability |
| Traditional classifier | Better at ranking or categorization | Needs a second mapping layer |
| LLM planner | Flexible and expressive | Costly, less deterministic |
The point is not that this approach beats every alternative. The point is that it is honest about what it can do. For a structured domain with a curated library, that is often enough.