MapTrace: Teaching models to walk a map without breaking it
MapTrace is a synthetic data machine for spatial reasoning. It teaches multimodal models to respect walls, corridors, and connectivity instead of drawing straight lines through whatever looks shortest.
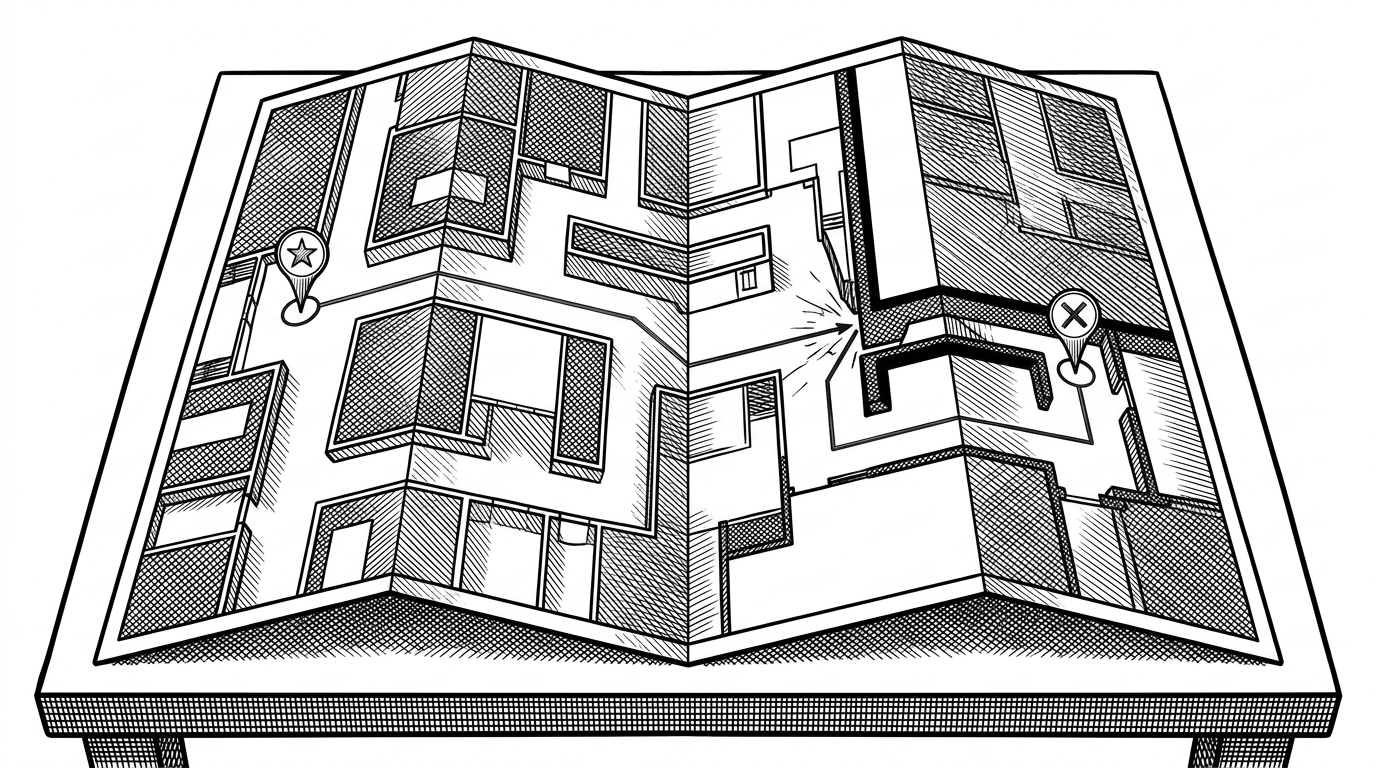
- MapTrace treats route tracing as a supervision problem, which makes spatial reasoning easier to scale than hand-labeling every map by hand.
- Its strongest move is the dataset, because critics, graphs, and path simplification turn messy images into compact training targets.
- The repo is engineered like a serious ML pipeline, with LoRA, FSDP, Flash Attention 2, and vLLM wrapped around a 27B model.
- The project matters only if synthetic routes improve real spatial performance, not just benchmark-sounding demos.
Most multimodal models can name the objects on a map. They fail when the question becomes physical: can you get from here to there without walking through a wall? MapTrace exists because that gap is still wide, and it is more useful to treat it as a data problem than as a model mysticism problem.
You can show a modern multimodal model a zoo map and it’ll tell you all about elephants and giraffes. But ask it to trace a walking route from the entrance to the reptile house? There’s a decent chance it’ll draw a line straight through an animal enclosure or a gift shop.
Why MapTrace exists
The paper behind MapTrace is blunt about the failure mode. It says multimodal large language models are strong at visual and textual reasoning, but still limited at fine-grained spatial understanding, especially route tracing on maps. That is the hole the project tries to fill, and it does it with synthetic supervision instead of a hand-built annotation factory.
While Multimodal Large Language Models have achieved human-like performance on many visual and textual reasoning tasks, their proficiency in fine-grained spatial understanding, such as route tracing on maps remains limited.
What is in the repo
The repository reads like a focused research pipeline, not a product shell. The engine room sits in src/, where postprocess_data.py cleans and compresses route data, finetune_gemma27b.py handles tuning, and vllm_inference.py handles evaluation and serving. Around that are the usual open-source edges, plus a distributed training config, and the stack is pure Python: PyTorch, Hugging Face transformers, trl, peft, pandas, pyarrow, shapely, Pillow, and vLLM.
The diagram matters because the project is not just about making maps. It is about building a closed loop where synthetic scenes, graph-based routes, and critic models combine to produce better labels than a human team could feasibly draw at scale. That is the real differentiator here, not any single model checkpoint.
The data pipeline is the product
The most interesting code lives in src/postprocess_data.py. It draws start and end markers directly onto the image, then simplifies the path with a Ramer-Douglas-Peucker style pass through shapely.geometry.LineString.simplify, which keeps the route shape while cutting it down to something a language model can actually learn. The coordinates are normalized to a 0.0 to 1.0 range and rounded to four decimals, which saves tokens without throwing away the geometry.
How it trains and serves
On the tuning side, finetune_gemma27b.py uses LoRA to hit the useful projection layers, then leans on Flash Attention 2 and FSDP to make a 27B model feasible without absurd hardware. The use of streaming dataset loading is a practical tell. This repo is built for a 210GB-scale dataset, not for a demo-sized notebook. On the inference side, vllm_inference.py uses multimodal processor settings and LoRARequest so the adapter can be applied cleanly at serving time.
| Approach | What it does well | What it fails to do |
|---|---|---|
| Prompt-only multimodal model | Describes map objects and reads landmarks | Often ignores walls, shortcuts through forbidden space, and loses topology |
| MapTrace-trained multimodal model | Learns semantically valid routes from synthetic supervision | Still depends on training coverage and image quality |
| Classic pathfinding graph | Finds optimal routes on an explicit graph | Does not understand raw images or natural language prompts |
| Manual annotation | Can capture nuance and intent | Does not scale to millions of routes |
That comparison is the point. MapTrace does not replace pathfinding, and it does not pretend that language models should magically infer geometry on their own. It teaches a multimodal model to inherit some of pathfinding’s discipline while still reading messy images and answering in language.